Platforms 13 min read
Is Cloudflare Blocking Googlebot or ChatGPT? The 2026 Settings
Most pages ranking for this were written before 15 September 2026 and describe a plan Cloudflare then changed. Here is what each setting does now, what happened to old settings, and how to test your own site.
Founder, SEO·AEO·GEO
Builds SEO·AEO·GEO and writes the crawler, schema, and citation research published here.
Key takeaways
- Since 15 September 2026, only the Training settings Block and Block on pages with ads stop Googlebot, Bingbot and Applebot; Disallow AI Training keeps them crawling for search.
- Cloudflare migrated every existing Training block to Disallow AI Training, so a training opt-out made before 15 September does not block Googlebot.
- ChatGPT search uses OAI-SearchBot, which Cloudflare files under Search and allows by default; GPTBot is the training crawler that Disallow AI Training blocks.
- A 402 Payment Required answer to AI crawlers comes from pay per crawl or a custom block response, and both are configured in AI Crawl Control.
- Outside tests send a crawler’s name, not its IP address, so a refusal is a lead to confirm in logs or Search Console, not a verdict.
Probably not, unless someone on your team chose Block. Since 15 September 2026, Cloudflare’s Training policy has four settings, and only Block and Block on pages with ads stop Googlebot, Bingbot and Applebot. Every training block that existed before that date was migrated to a third setting, Disallow AI Training, which keeps those three crawling for search while refusing training-only crawlers such as GPTBot and ClaudeBot. ChatGPT search runs on a different crawler, OAI-SearchBot, which Cloudflare files under Search and allows by default.
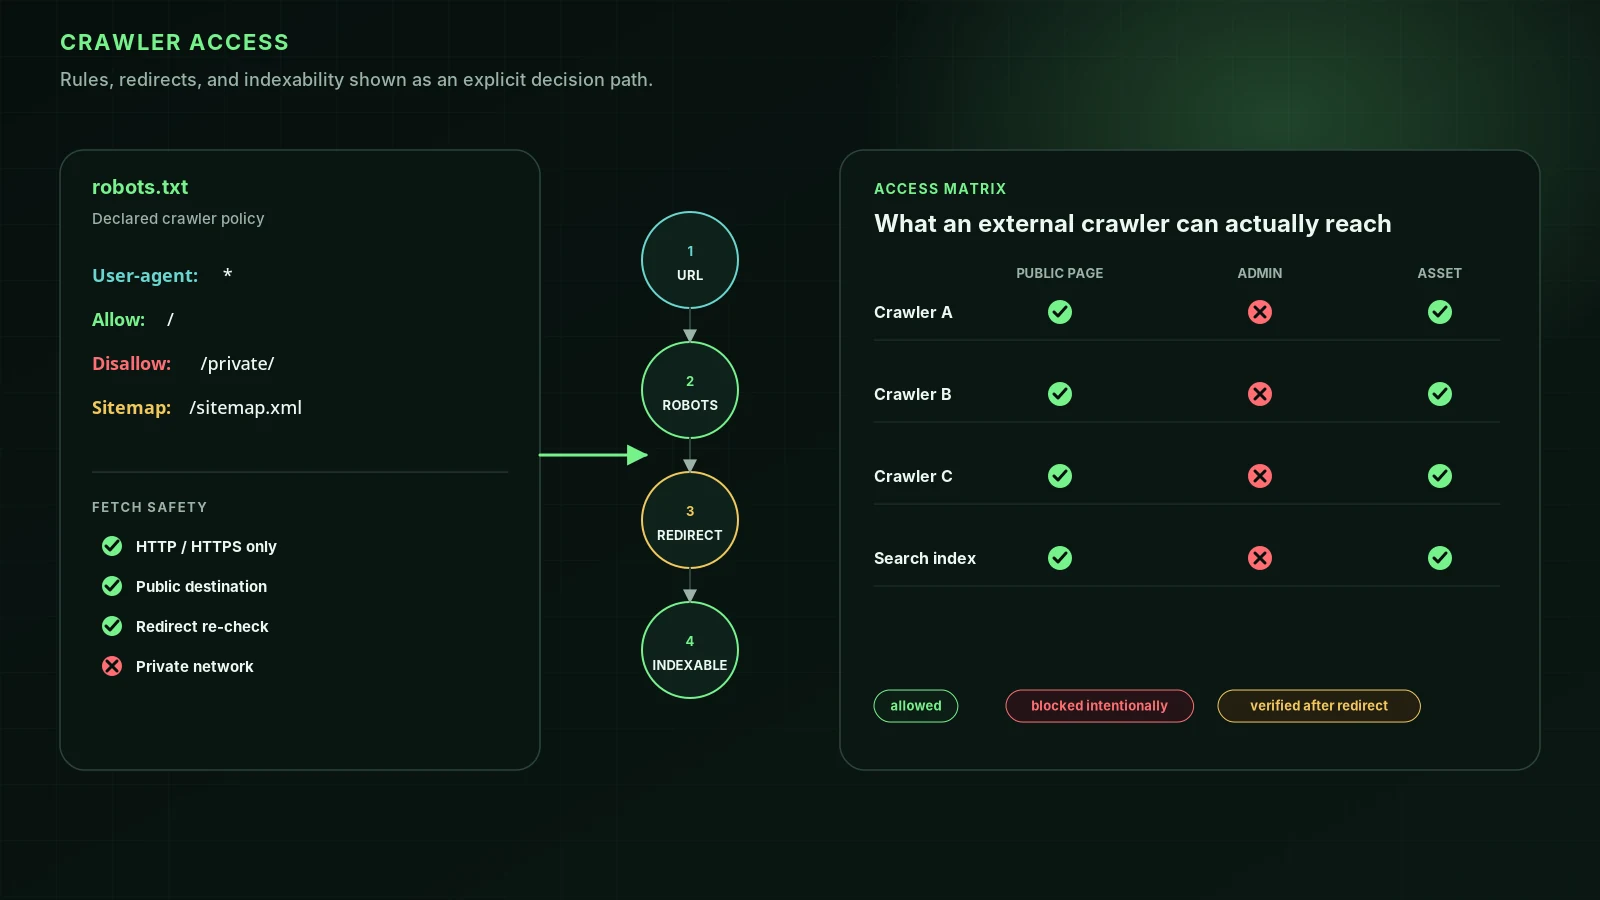
To check, open your domain in the Cloudflare dashboard, go to Security Settings, filter by Bot traffic and open Configure AI bot policies. If Training says Block, Google cannot crawl you. Then look at AI Crawl Control’s crawler list for bots blocked one by one. The rest of this page explains each setting, what happened to old settings, and how to test from outside. Every Cloudflare page cited here was re-read on 13 October 2026.
What changed on 1 July and 15 September 2026
Cloudflare has changed its AI crawler controls repeatedly since July 2025. The 1 July 2026 announcement is the one most guides still describe, and it is no longer accurate.
| Date | What Cloudflare did | Effect on Googlebot, Bingbot, Applebot |
|---|---|---|
| 1 Jul 2025 | Announced it was “changing the default to block AI crawlers unless they pay creators for their content”, via a one-click Block AI bots option. | Not blocked: Block AI bots excluded mixed-purpose crawlers. |
| 24 Sep 2025 | Added the Content Signals Policy to managed robots.txt (Content-Signal: search=yes, ai-train=no). | None: a statement of preference, not a block. |
| 1 Jul 2026 | Launched Search, Agent and Training policies on every plan, stopped treating Verified bots as allowed by default, and announced that from 15 September any Training block would also block mixed-purpose crawlers. | Announced: would be blocked by any Training block. |
| 15 Sep 2026 | Added Disallow AI Training; made Block and Block on pages with ads cover mixed-use crawlers; deprecated legacy Block AI bots and managed robots.txt in favour of Bot Preference Sync; migrated old Training blocks to Disallow AI Training. | Blocked only by Block or Block on pages with ads. |
The 1 July 2026 post said plainly that “multi-purpose crawlers such as Googlebot, Applebot, and BingBot will be blocked by customers who have selected to block Training”. Articles written between July and mid-September, the “check this before September 15” genre, repeated that forecast. Cloudflare’s own Block AI Bots documentation page, last updated 1 July 2026, still says it. The 15 September announcement replaced it:
Block and “Block on pages with ads” now apply to mixed-use crawlers, including Applebot, Bingbot, and Googlebot, so either setting impacts search as well as training. To stop training and keep search, use Disallow AI Training.
Disallow AI Training vs Block: which spares Googlebot
Cloudflare now sorts bots by behaviour. Search means building an index. Training means training or fine-tuning a model. Agent means fetching a page for a person in real time, such as a chat assistant reading a link. A mixed-use crawler does Search and Training under one user agent, and the ones that matter are Googlebot, Bingbot and Applebot. The Training policy is where they get caught.
| Training setting | Training-only crawlers (GPTBot, ClaudeBot, Meta-ExternalAgent and others) | Googlebot, Bingbot, Applebot | What is published |
|---|---|---|---|
| Allow | Allowed | Allowed | Nothing |
| Disallow AI Training | Blocked at the edge | Allowed for search | No-training directives in robots.txt via Bot Preference Sync |
| Block on pages with ads | Blocked on pages Cloudflare detects as showing ads | Blocked on those pages, search included | Managed directives |
| Block | Blocked everywhere | Blocked everywhere, search included | Managed directives |
If you want mixed-use crawlers gone entirely, you now have to say so. Select Block. It will stop Applebot, Bingbot, and Googlebot from reaching your site — search included.
There is no Disallow AI Training for pages with ads: Cloudflare says that page list is too large and changes too often to write into robots.txt.
How each mixed-use crawler honours a training opt-out
- Googlebot: the training opt-out is the Google-Extended token in robots.txt. Google says Google-Extended “does not impact a site’s inclusion in Google Search nor is it used as a ranking signal in Google Search.”
- Applebot: the training opt-out is Applebot-Extended. Apple says “Webpages that disallow Applebot-Extended can still be included in search results.”
- Bingbot: there is no robots.txt training token yet. Cloudflare says Microsoft is building one, “targeted for early 2027”, and that until then “selecting Disallow AI Training will not automatically convey a no-training preference to Bing through robots.txt.” Bing’s existing control is the noarchive meta tag.
Cloudflare calls operators that meet its requirements “Accountable”: Apple, Google and Microsoft for their mixed-use crawlers, and Amazon, Anthropic, Meta and OpenAI because they run separate search and training crawlers that can be blocked independently.
Is Cloudflare blocking ChatGPT, Perplexity or Claude?
Each AI company sends more than one bot, and Cloudflare files them under different behaviours. Which one is refused depends on which policy you changed.
| Bot | Job | Cloudflare behaviour | Refused when |
|---|---|---|---|
| GPTBot, ClaudeBot | Collects training data | Training | Training is Disallow AI Training, Block on pages with ads, or Block |
| OAI-SearchBot, Claude-SearchBot, PerplexityBot | Builds the index behind ChatGPT search, Claude and Perplexity answers | Search | Search is Block or Block on pages with ads, or the bot is blocked by name in AI Crawl Control or a WAF rule |
| ChatGPT-User, Claude-User, Perplexity-User | Fetches a page because a person asked | Agent | Agent is Block, or Block on pages with ads on pages showing ads |
So the usual Disallow AI Training setup blocks GPTBot and leaves ChatGPT search alone. That matches OpenAI’s own split: “Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers”, while GPTBot only governs training. Our guide to GPTBot vs OAI-SearchBot covers the robots.txt side. Cloudflare used to list OAI-SearchBot under a separate “AI Search” category; its verified-bots documentation now says “there is no longer a meaningful distinction between ‘AI Search’ and traditional search”, and both are treated as Search.
Two details catch people out. First, since 1 July 2026 Verified no longer means allowed by default; in Cloudflare’s words, “the allowed category (e.g., allowing Search) will determine what is allowed to access a website.” Second, the preset Cloudflare offers new ad-funded domains sets Agent to Block on pages with ads, so a ChatGPT-User fetch of an article that shows ads is refused. That is a deliberate trade-off for publishers who earn from human attention. For a business that wants to be recommended, it is usually the wrong one.
Were your old settings migrated?
Yes, automatically, and in the safe direction. Cloudflare’s 15 September post publishes the mapping:
| Setting before 15 September | Search after | Training after | Agent after |
|---|---|---|---|
| Legacy Block AI bots: off | Allow | Allow | Allow |
| Legacy Block AI bots: Block | Allow | Disallow AI Training | Block on pages with ads |
| Legacy Block AI bots: Block on pages with ads | Allow | Disallow AI Training | Block on pages with ads |
| Granular Training: Block or Block on pages with ads | Unchanged | Disallow AI Training | Unchanged |
No zone went from “training blocked” to “Googlebot blocked” on 15 September by itself. A zone refuses Googlebot today only if someone selected Block or Block on pages with ads for Training after the change, or blocked Search. Under the new definitions Block covers mixed-use crawlers whichever policy it is set on, so a Search policy that was already on Block deserves a second look. Note the side effect for legacy Block AI bots users: Agent moved to Block on pages with ads, which affects assistant fetches such as ChatGPT-User. New domains get one of two presets during onboarding:
| Setting | Site without ads | Site monetised with ads |
|---|---|---|
| Bot Preference Sync | Enabled | Enabled |
| Search | Allow | Allow |
| Training | Allow | Disallow AI Training |
| Agent | Allow | Block on pages with ads |
What Cloudflare’s managed robots.txt says
When Bot Preference Sync is on and at least one policy restricts something, Cloudflare writes directives into your robots.txt. If your origin already returns a robots.txt with HTTP 200, Cloudflare prepends its block to your file. This is the managed content as Cloudflare documents it (page updated 8 October 2026), which follows a commented policy text:
# BEGIN Cloudflare Managed content

User-Agent: *
Content-signal: search=yes, ai-train=no, use=reference
Allow: /

User-agent: Amazonbot
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: Bytespider
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: GPTBot
Disallow: /

User-agent: meta-externalagent
Disallow: /

# END Cloudflare Managed Content
Three things to notice. The User-Agent: * group keeps everything allowed, and the Disallow lines name training crawlers and training control tokens only; Google-Extended and Applebot-Extended never fetch pages, so disallowing them removes nothing from Search. Amazonbot is listed because Amazon says it “may be used to train Amazon AI models”; Amazon’s search crawler is a separate bot, Amzn-SearchBot, covered in Meta-WebIndexer, Amzn-SearchBot and the new AI crawlers. And the Content-signal line is a statement of preference that no major AI crawler documents reading, as our Content-Signal explainer shows.
Cloudflare is explicit that the file is not the enforcement: “robots.txt compliance is voluntary.” The edge block is what actually stops a crawler, and it runs whether or not the crawler reads your robots.txt.
Cloudflare’s own sites take a different line. When we fetched www.cloudflare.com/robots.txt on 13 October 2026, it explicitly allowed GPTBot, ChatGPT-User, Google-Extended, CCBot and PerplexityBot and ended with this declaration; blog.cloudflare.com and developers.cloudflare.com carried the same Content-Signal line:
# Robots.txt for www.cloudflare.com (excerpt, fetched 13 Oct 2026)
User-agent: GPTBot
Allow: /

User-agent: Google-Extended
Allow: /

User-agent: CCBot
Allow: /

# Content Signals — declare AI content usage preferences
Content-Signal: ai-train=yes, search=yes, ai-input=yes
The example domain in Cloudflare’s documentation, crawlstop.com, returned its plain four-rule file with no managed block on the same day. Read your own live file, not the documentation.
How to check your own zone
In the Cloudflare dashboard (five minutes)
- Select the domain, go to Security Settings, filter by Bot traffic and open Configure AI bot policies. Note the Search, Training and Agent values. Training set to Block or Block on pages with ads means Googlebot, Bingbot and Applebot are refused, everywhere or on ad pages.
- Check whether Bot Preference Sync is on. It is what publishes your Training choice into robots.txt.
- Open AI Crawl Control and read the Crawlers list. Each crawler has its own Allow or Block action, and a block set here creates a WAF custom rule. Make sure OAI-SearchBot, Claude-SearchBot and PerplexityBot are not set to Block. The Robots.txt violations column shows crawlers ignoring your file.
- Read your WAF custom rules. AI Crawl Control’s rule appears there, and hand-written rules that match user agents or bot categories can refuse crawlers your policies allow.
- For Google, use Search Console. Google’s troubleshooting advice is to use the URL Inspection tool “to see the HTML that Googlebot received while crawling the page.” It is the only check here made by the real crawler from Google’s own IP addresses.
From outside, with curl (two minutes)
Compare what a browser and a request carrying a crawler’s name get for the same URL. Replace example.com with your page.
# 1. Status code for a browser user-agent
curl -s -o /dev/null -w "%{http_code}\n" \
  -A "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/141.0 Safari/537.36" \
  https://example.com/

# 2. Status code for a request that calls itself OAI-SearchBot
curl -s -o /dev/null -w "%{http_code}\n" \
  -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot" \
  https://example.com/

# 3. Is Cloudflare in front, and did it challenge the request?
curl -sI -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot" \
  https://example.com/ | grep -i "^server\|^cf-ray\|^cf-mitigated"

# 4. Print the managed block from your live robots.txt
curl -s https://example.com/robots.txt | sed -n "/BEGIN Cloudflare Managed/,/END Cloudflare Managed/p"
Read the result as a lead. A 200 for both means no user-agent rule stands in the way. A 403, a cf-mitigated: challenge header or a 402 for the crawler but not the browser means a rule exists, or that Cloudflare spotted a request claiming to be a crawler without coming from that crawler’s IP addresses. The difference matters, and the last section explains why.
What a 402 Payment Required means
Pay per crawl lets a site charge AI crawlers per request. Cloudflare says each crawler either presents payment intent in request headers for an HTTP 200, or receives “an HTTP 402 Payment Required response with pricing”, with Cloudflare acting as merchant of record. It is “currently in closed beta”. Separately, on paid plans AI Crawl Control lets you choose what a blocked crawler receives: 403 Forbidden, or 402 Payment Required for when “the AI crawler must pay to access your content”, plus a custom body. A WAF or Bot Management block overrides a charge.
We saw this live. On 13 October 2026, investopedia.com and allrecipes.com, two sites from the same publisher, returned 200 to a browser user-agent and 402 to requests identifying as OAI-SearchBot and GPTBot. The response, trimmed:
HTTP/1.1 402 Payment Required
Date: Tue, 13 Oct 2026 16:31:02 GMT
Content-Type: text/html
Server: cloudflare
CF-RAY: a49fbb75ab153ee3-BOM

<p>
  If you would like to access our content for licensing, please contact
  <a href="mailto:contentlicensing@people.inc">contentlicensing@people.inc</a>.
</p>
The response carried no pricing header, so it looks like a custom 402 block response rather than a priced pay-per-crawl offer. From outside we cannot see the zone’s configuration, and our requests did not come from OpenAI’s IP addresses. If your own site answers AI crawlers with 402 and you did not mean to charge them, check AI Crawl Control’s block response setting.
What our audit detects, and the simulated user-agent limit
Our free audit and the AI crawler checker detect Cloudflare from the cf-ray and server headers, read your robots.txt including any managed block and Content-Signal line, and request the page as OAI-SearchBot, PerplexityBot and Claude-SearchBot alongside a browser request. If the crawler requests get a 403, a challenge page or a 402 while the browser gets the page, we report an edge-access problem.
What the test cannot do is be the real crawler. Real crawlers are verified by IP address, reverse DNS or a Web Bot Auth signature, and a CDN can treat a request that merely uses a crawler’s name differently from the crawler itself. An example from the same day: stackoverflow.com, served through Cloudflare, answered our robots.txt requests with HTTP 418 and a deny-everything file, whether we sent a browser string, “OAI-SearchBot” or “Googlebot”. Stack Overflow pages plainly appear in Google, so the real Googlebot is not getting that answer. A borrowed name earns no trust.
So read our result asymmetrically. If the simulated crawler gets the page, no user-agent rule is blocking it, which is good evidence. If it is refused, treat that as a strong lead and confirm in Cloudflare’s security events or your server logs that the real bot gets a 200. Cloudflare notes that on the Free plan, AI Crawl Control “identifies AI crawlers based on their user agent strings”, so on Free zones a user-agent test is closer to what the real crawler meets.
One more limit, stated in our methodology: when we see Cloudflare plus ai-train=no, we prompt you to check the Training setting. That is a prompt, not evidence of a Googlebot block. Ai-train=no is exactly what Disallow AI Training publishes, and that setting spares mixed-use crawlers.
Which setting should you pick?
| If you want | Search | Training | Agent |
|---|---|---|---|
| To be found in Google, Bing, ChatGPT and Perplexity, and you accept training | Allow | Allow | Allow |
| The same, without training | Allow | Disallow AI Training | Allow |
| Ad-funded pages protected from assistants that skip the visit | Allow | Disallow AI Training | Block on pages with ads |
| No mixed-use crawlers at all, accepting you leave Google, Bing and Apple search | Allow | Block | Your choice |
Two things Cloudflare cannot do for you yet. It cannot keep you out of AI Overviews while leaving you in Google Search; Cloudflare says AI-summary controls are its next goal, “by early next year”. Today that is Google’s Search Console setting or nosnippet, covered in AI Overviews eligibility: nosnippet, Google-Extended and the opt-out. And no setting makes an AI system cite you: access is the precondition, not the lever. For the rest of the access checklist, including robots.txt per bot, raw HTML and response health, see Can ChatGPT, Claude and Perplexity read your website?.
FAQ
Is Cloudflare blocking Googlebot on my site?+
Only if your zone’s Training policy is set to Block or Block on pages with ads, your Search policy is set to Block, or a custom WAF rule targets Googlebot. Since 15 September 2026 the common Disallow AI Training setting keeps Googlebot, Bingbot and Applebot allowed for search. Check Security Settings, then Configure AI bot policies, and confirm with Search Console’s URL Inspection live test.
Does Cloudflare’s AI bot blocking stop ChatGPT search?+
Not by default. ChatGPT search relies on OAI-SearchBot, which Cloudflare classifies as Search, and Search is allowed unless you block it or block the bot individually in AI Crawl Control. The Training settings block GPTBot, which OpenAI says is independent of search inclusion.
What is the difference between Disallow AI Training and Block in Cloudflare?+
Disallow AI Training publishes a no-training preference in robots.txt, blocks training-only crawlers at the edge, and leaves mixed-use crawlers such as Googlebot, Bingbot and Applebot allowed for search. Block refuses every training crawler, including those three, so it removes you from Google, Bing and Apple search as well.
Did Cloudflare change my settings on 15 September 2026?+
It migrated them. Legacy Block AI bots users and anyone with a Training block moved to Disallow AI Training, and legacy Block AI bots users also had Agent set to Block on pages with ads. Search kept its previous value. No Training setting was migrated to the stricter Block.
Why do AI crawlers get a 402 Payment Required from my site?+
Either pay per crawl is active, which is in closed beta and answers crawlers that have not agreed to pay with a 402 and a price, or AI Crawl Control is configured to return 402 instead of 403 when it blocks a crawler. Both settings live in AI Crawl Control.
Does Disallow AI Training stop Bing from training on my content?+
Not yet. Cloudflare says Microsoft is building a robots.txt no-training preference targeted for early 2027, and until then Disallow AI Training does not convey a no-training preference to Bing. Bing’s current control is the noarchive meta tag.
Sources
- Have it both ways: stay discoverable in search while disallowing AI training — Cloudflare Blog (2026-09-15)
- Your site, your rules: new AI traffic options for all customers — Cloudflare Blog (2026-07-01)
- Content Independence Day: no AI crawl without compensation! — Cloudflare Blog (2025-07-01)
- Giving users choice with Cloudflare’s new Content Signals Policy — Cloudflare Blog (2025-09-24)
- Block AI Bots — Cloudflare Docs (2026-07-01)
- robots.txt setting (managed robots.txt and Bot Preference Sync) — Cloudflare Docs (2026-10-08)
- Verified bots — Cloudflare Docs (2026-10-08)
- What is Pay Per Crawl? — Cloudflare Docs (2026-07-28)
- Manage AI crawlers — Cloudflare Docs (2026-07-28)
- Overview of OpenAI crawlers — OpenAI
- Google’s common crawlers (Google-Extended) — Google Search Central (2026-07-14)
- AI features and your website — Google Search Central (2025-12-10)
- About Applebot — Apple (2026-09-04)
- Amazonbot and Amzn-SearchBot — Amazon Developer
Run it on your domain
See this lens as a finding, not a lecture.
Free technical GEO audit. Evidence-traced scores, LLM-ready export, no login.
Audit your website